From Assignment to Productionised Data Science Delivery System: DSquared Transient Population Demand Pilot

Introduction

In this blog, I want to reflect on my assignment on productionising data science delivery. The aim was to explore how data science work can move beyond exploratory notebooks and become a structured, repeatable and explainable workflow.

I used transient population demand in DMAs, as the demonstration case. In water demand analysis, transient population refers to people who are temporarily present in an area but are not fully represented in resident population figures. This may include tourists, day visitors, commuters, students, seasonal occupants, event attendees and people staying in short-term accommodation.

The assignment had three connected aims:

  • to develop a structured approach to data science delivery;
  • to demonstrate that approach through a transient demand analysis;
  • to understand how external data sources can improve the quality of interpretation.

The blog follows the development of the assignment: I started with a question, learned how to turn it into a productionised workflow, and came up with a repeatable process for identifying and explaining transient population-like demand uplift.

Story

I started with the question:

Can temporary population movement help explain unusual increases in DMA demand?

At first, this seemed straightforward. If demand increased during a holiday period, tourist season or local event, transient population might be part of the explanation. However, the more I explored the problem, the clearer it became that high demand does not have a single cause. I therefore reframed the question into something more measurable:

Is demand higher than expected, and is the timing or shape of that uplift consistent with transient population effects?

This reframing was important. It moved the assignment away from trying to prove a direct cause and towards building an evidence-based interpretation.

I developed a productionised delivery workflow

The wider learning objective was to productionise the way the analysis was delivered. I wanted to move from a one-off notebook exercise to a workflow that could be rerun, reviewed and adapted. The aim is to produce a data science delivery system, which I will aptly call, DSquared, giving us the delivery structure:

Intake → Planning → Pipeline → Experiments → Results → Deployment → Governance

Each stage had a purpose. Intake clarified the question. Planning defined the data and outputs. The pipeline made the workflow repeatable. Experiments allowed analytical methods to be tested. Results translated outputs into interpretation. Deployment considered how the workflow could be rerun or scheduled. Governance captured assumptions, risks and limitations.

This changed the assignment from a collection of codes and charts into a documented delivery process with a clear problem, method and output.

I used transient demand as the demonstration case

The analytical method was based on a baseline-and-uplift approach.

First, I estimated expected demand using available explanatory features such as weather, seasonality and calendar effects. I then compared observed demand with this expected baseline.

In simple terms:

Observed demand − Expected baseline demand = Possible uplift

Where observed demand was above the baseline, the positive difference was treated as candidate uplift. The aim was not to directly count temporary people. Instead, the aim was to identify periods where demand was unusually high after controlling for known conditions and then assess whether the surrounding evidence was consistent with transient population activity.

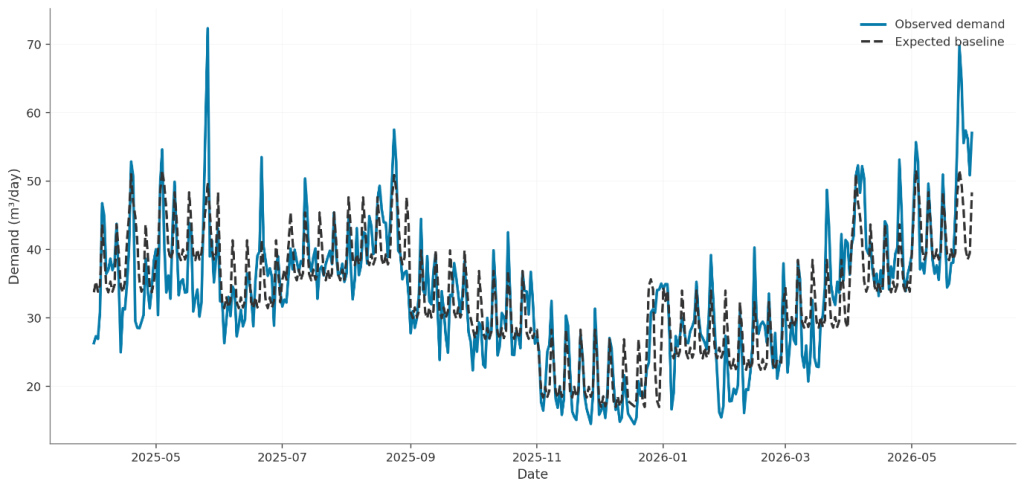
Figure 1: Observed Demand Compared with Expected Baseline

Figure 1 compares observed daily DMA demand with the expected baseline demand. The baseline provides a reference point for identifying periods where demand was higher than expected, rather than simply high in absolute terms.

This figure shows the central comparison in the analysis: observed demand against expected baseline demand. It changes the question from “Was demand high?” to “Was demand higher than expected?”

That distinction matters because a high-demand day may still be normal under certain conditions, such as warm weather or seasonal activity. The baseline provides the reference point needed for a more responsible interpretation.

I learned why external data matters

A key learning point was that water demand data from internal source (client) is not enough on its own. A DMA flow time series can show that demand changed, but it does not fully explain why.

To strengthen the analysis, I considered external data sources that could provide context, including:

  • weather data;
  • bank holiday calendars;
  • school holiday periods;
  • tourism indicators;
  • pageview or search-interest proxies;
  • event data;
  • traffic indicators;
  • accommodation or short-term-let data;
  • local footfall data where available.

This introduced an important data engineering and ETL (extract, transform, load) component. Each source may have a different format, frequency, spatial coverage and reliability. Some data may be daily, some event-based, some API-based and some stored as CSV files or database tables.

This raised practical ETL questions:

  • How should each source be collected?
  • How should dates, time zones and locations be standardised?
  • How should missing or incomplete values be handled?
  • How should daily external data be joined to 15-minute internal flow data?
  • How should source coverage and reliability be reported?
  • How should the workflow remain repeatable if external sources change?

The ETL process can be summarised as:

Extract external data → standardise fields → clean missing values → transform into daily features → join with DMA demand → check coverage → use in analysis

This was one of the most important lessons from the assignment. Data engineering is not separate from data science. In this use case, the quality of the interpretation depends directly on the quality of the data pipeline.

I built evidence around the uplift signal

After identifying uplift, the next step was to examine the supporting evidence. A positive uplift does not explain itself. It needs to be checked against other signals.

I considered whether uplift aligned with:

  • holidays;
  • warm or dry weather;
  • tourism-related indicators;
  • local events;
  • traffic or footfall proxies;
  • changes in daily demand shape;
  • possible operational or data quality issues.

This evidence-building step was central to the assignment. It showed that a data science workflow should not only produce a signal; it should also guide interpretation.

A careful conclusion would be:

The DMA shows demand uplift above a controlled baseline, with timing and profile shape consistent with transient population effects, subject to data coverage and operational review.

Figure 2: Transient Intensity Over Time

Figure 2 shows the Transient Intensity Index over time. The index normalises uplift against expected baseline demand so that stronger periods can be reviewed more consistently.

This figure shows how uplift changes over time after being normalised against expected baseline demand. It helps identify the periods where the transient population-like signal is strongest.

The practical value of this view is that it narrows a long time series into specific periods for review. These periods can then be checked against holidays, events, weather, tourism indicators and operational records.

I learned to analyse the shape of demand

Daily volume shows how much water was used, but it does not show when demand occurred. This matters because different causes can produce different daily profiles.

For example, leakage may appear as elevated night flow, while visitor-related demand may appear more strongly during daytime or evening periods. By analysing 15-minute profiles, I added another layer of interpretation.

I was no longer asking only whether demand increased. I was also asking whether the behaviour of demand changed.

Figure 3: Demand Profile by Uplift Level

Figure 3 compares median 15-minute demand profiles grouped by transient intensity level. The profile view helps assess whether higher-intensity periods show a different daily demand shape.

This figure compares demand profiles for lower and higher uplift periods. It helps answer:

Do high-uplift days look different from normal days?

A change in profile shape does not prove the cause of uplift, but it provides useful supporting evidence. It helps distinguish potentially visitor-like demand from other explanations such as leakage, operational changes or data quality problems.

I came up with a repeatable process

By the end of the assignment, I had developed a repeatable process for analysing transient-like demand uplift:

Define the question → identify internal and external data sources → extract and transform contextual data → prepare demand features → estimate expected demand → calculate uplift → assess supporting evidence → generate interpretable outputs → document assumptions and limitations

This became the main product of the assignment. The transient population demand analysis was the demonstration case, but the workflow itself is reusable. It could be applied to other DMAs, other time periods or other operational questions where the aim is to separate expected behaviour from unusual behaviour.

Several lessons emerged.

First, problem framing matters. Asking whether visitors caused high demand is difficult to answer directly. A better question is whether the observed uplift is consistent with transient population effects.

Second, external data improves interpretation. Internal demand data shows the signal, while external data provides context. Weather, holidays, events, tourism indicators and traffic proxies can help explain when unusual demand occurs.

Third, data engineering is part of the analytical method. External data must be collected, cleaned, transformed, aligned and checked before it can support interpretation.

Fourth, repeatability matters. A workflow that only exists in a notebook is difficult to review or reuse. A structured pipeline makes the work more dependable, especially when multiple data sources and client-specific configurations are involved.

Finally, governance is part of delivery. Assumptions, risks, source limitations and interpretation boundaries need to be visible so that the analysis can be understood and improved.

There are also important limitations. Many external sources are proxies. Weather, holidays, pageviews, traffic indicators and event data can provide useful context, but they do not directly measure the number of temporary people present in a DMA.

External data also introduces its own risks. APIs may change, data may be incomplete, spatial coverage may not align with DMA boundaries, and some indicators may reflect interest rather than physical presence. Source health, coverage and relevance therefore need to be checked as part of the workflow.

High demand can also have non-transient causes. Leakage, operational activity and data quality issues must be reviewed before interpreting uplift as visitor related. For this reason, I describe the output as transient population like demand uplift, rather than proof of transient population demand.
Conclusion

In this assignment, I explored how data science delivery can become more structured, repeatable and explainable, using transient population demand analysis as the demonstration case.

I started with a broad question about unusual DMA demand and whether temporary population movement could help explain it. I then reframed the question into a more responsible analytical task: identifying demand above an expected baseline and assessing whether the timing and pattern were consistent with transient population effects.

I learned and developed a productionised workflow that combined internal DMA demand data, external contextual data, ETL, baseline modelling, uplift analysis, profile-shape evidence and clear reporting. This helped move the work beyond exploratory analysis and towards a process that could be rerun, reviewed and adapted.

The main outcome was not only the analysis itself, but the delivery structure behind it. The assignment showed how data science work can be organised so that it is easier to repeat, explain, govern and improve.

In that sense, my DSquared transient demand assignment became both an analytical exercise and a demonstration of productionised data science delivery, supported by external data enrichment and practical ETL learning.

Related articles